Forgepulse
Machines that warn you weeks before they fail.
- Client
- Draycott Precision Engineering
- Year
- 2023
- Duration
- 10 months
- Team size
- 8 engineers
Interactive Demo
A hands-on mock of the product we built — click around.
Demo interface shown in English.
The challenge
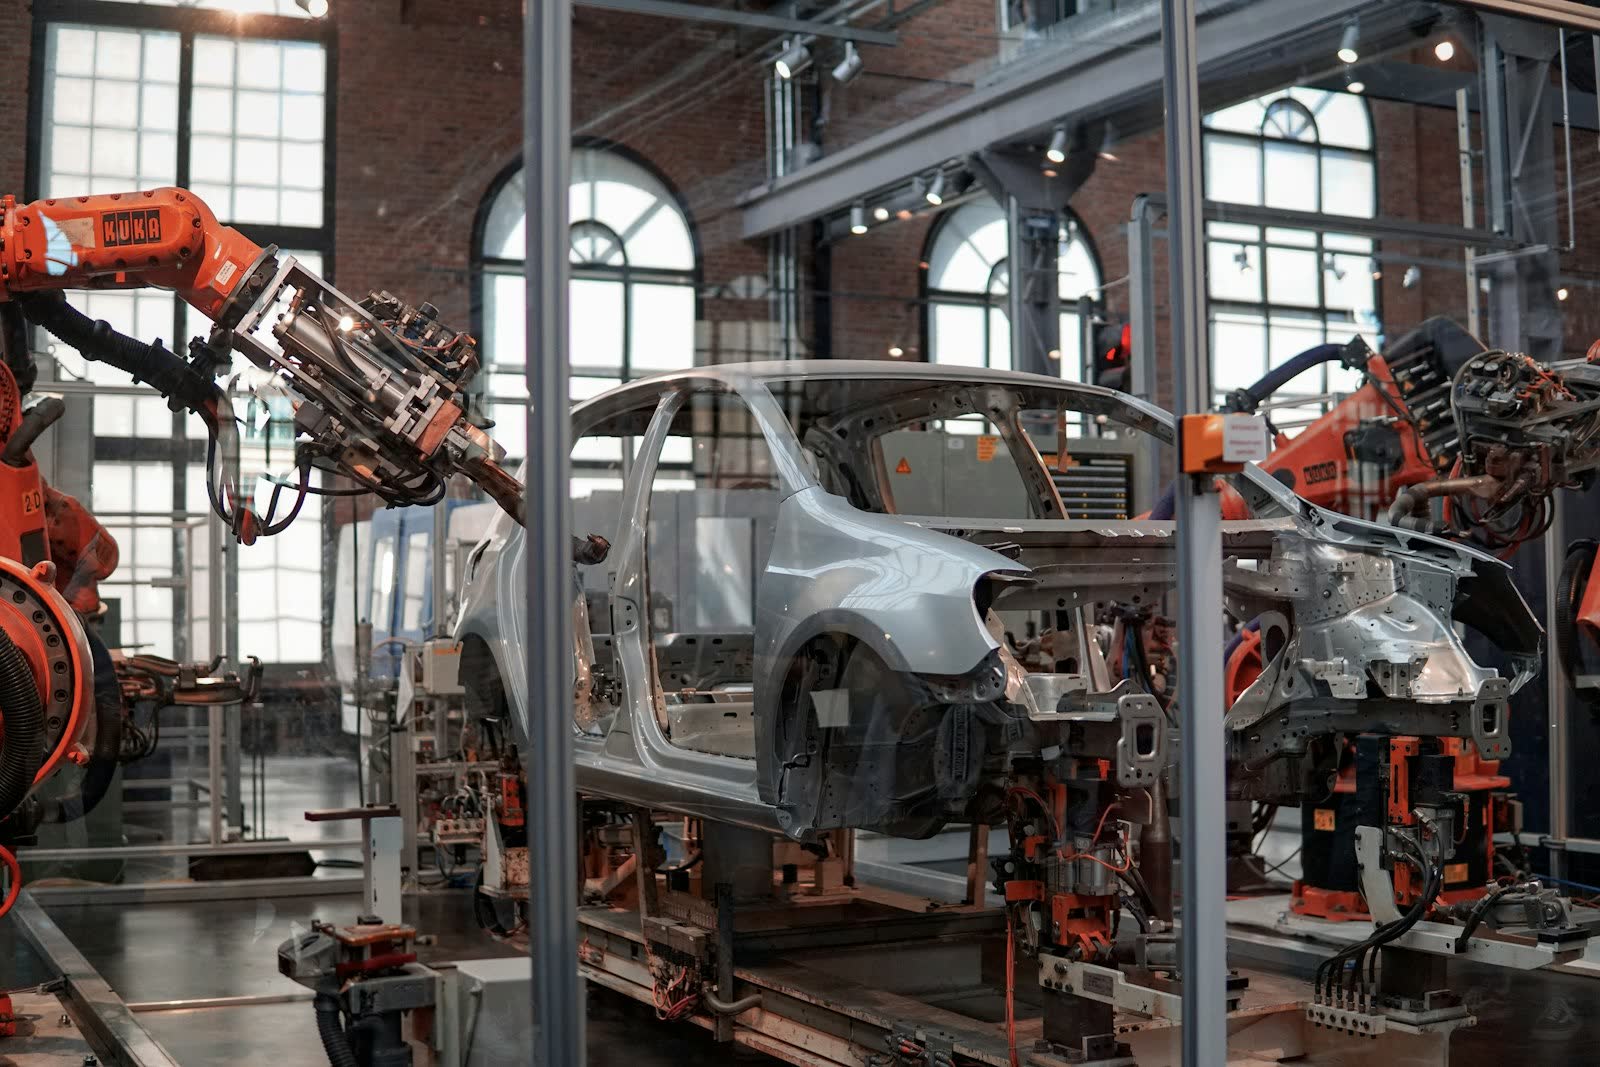
Draycott’s three halls ran 64 CNC machines around the clock for aerospace clients with penalty-laden delivery schedules. Unplanned downtime cost roughly £18,000 per machine-hour once scrapped parts, re-machining and late-delivery penalties were counted — and maintenance was purely calendar-based, so bearings were replaced too early or catastrophically too late. The shop floor was a hostile environment: coolant mist, metal swarf, forty-year-old machines with no network port alongside brand-new five-axis centres, and Wi-Fi that dropped whenever the big presses ran. Any sensor network had to retrofit without stopping production, survive the environment, and keep working when connectivity did not.
Our solution
We deployed battery-backed edge gateways running K3s that read vibration and current sensors over MQTT and legacy machines over OPC-UA, buffering up to 72 hours of data locally when the network drops. Time-series data lands in TimescaleDB, where Python models — isolation forests per machine family, retrained weekly on labelled failure history — score every asset hourly and raise alerts with an eleven-day median lead time. A React dashboard shows machine health as a single traffic light per asset, drillable to raw spectra for the reliability engineers, and alerts route by SMS and Teams to the shift lead on duty. The first predictive catch, a spindle bearing, paid for the pilot twelve times over.
Results
Technology stack
Facing a similar challenge?
We've solved this class of problem before. Let's talk about how that experience applies to your situation.
Discuss your projectNext case study
Prismcast →